
Crop Model API Review for Agronomy Teams
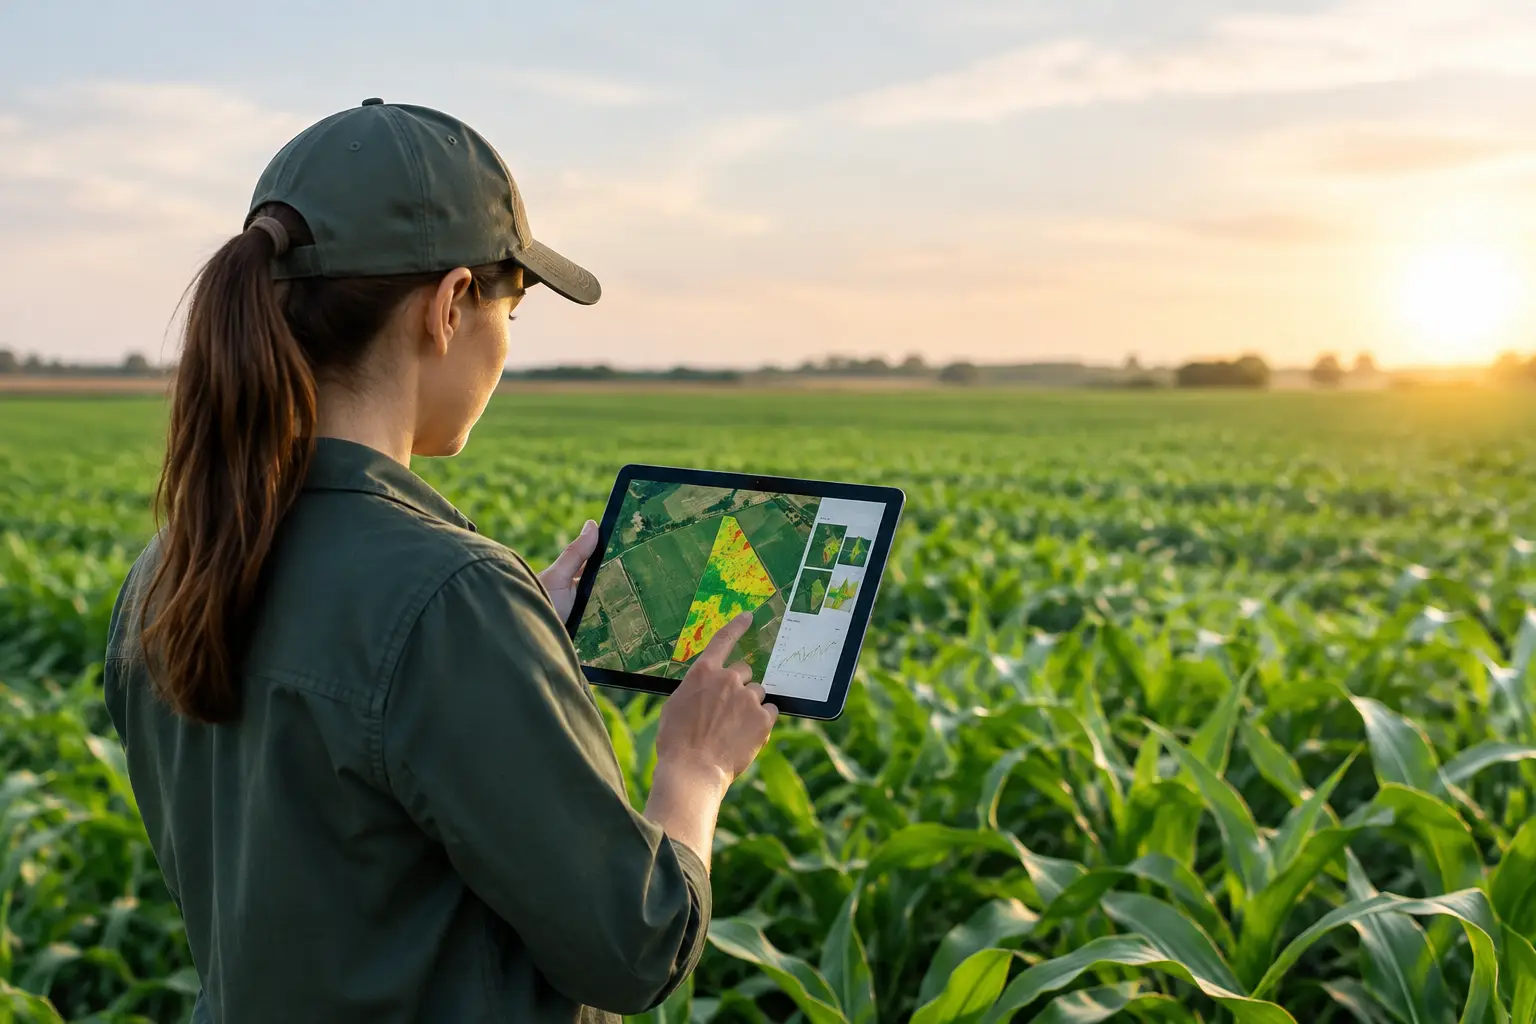
A crop model API can look convincing in a product demonstration: a field boundary goes in, daily recommendations or risk scores come out. A serious crop model API review starts where the demonstration ends. Can the model represent the crop, soil, irrigation system, climate, and management conditions that drive decisions in your production program? And can its output be operationalized without creating false precision across hundreds or thousands of fields?
For commercial farming operations, grower networks, and agricultural companies, the question is not whether an API returns a value. The question is whether that value improves irrigation timing, nitrogen management, phenology planning, field scouting, or grower compliance under real operating constraints.
What a Crop Model API Should Actually Deliver
The term crop model covers several different tools. Some APIs estimate reference evapotranspiration, then apply crop coefficients to calculate crop water use. Others simulate phenology from temperature accumulation, predict biomass or yield, estimate nitrogen demand, or calculate pest and disease risk from weather. Satellite-derived vegetation indicators are often presented alongside these outputs, but they are observations or proxies, not crop models by themselves.
A useful API may combine several of these functions. That does not mean every output should be treated as a recommendation. ETc can support an irrigation balance, for example, but irrigation scheduling still requires effective rainfall, irrigation application records, root-zone depth, allowable depletion, salinity, soil texture, and system constraints. A phenology model may estimate a key growth stage, yet local cultivar, planting date, chilling exposure, canopy conditions, and unusual weather can materially shift the result.
The first review task is to define the decision the API will support. “Improve agronomy” is not a requirement. “Identify drip-irrigated almond blocks that are likely to exceed target depletion within the next four days” is a requirement. So is “prioritize maize fields for nitrogen-status inspection before sidedress decisions” or “flag tomato fields entering a disease-favorable weather window.” Specific decisions expose whether the model has the necessary inputs and whether its output has a clear user and action.
Crop Model API Review: Start With Agronomic Fit
A model that performs acceptably in a broad crop category can still be unsuitable for a commercial program. “Citrus,” “vegetables,” or “grains” are not sufficiently precise categories for high-value management decisions. Review crop coverage at the level that matters: species, cultivar or maturity group where relevant, production system, planting or pruning system, and season.
For perennial crops, ask how the model handles carryover effects, canopy development, crop load, alternate bearing, and rooting depth. For annual crops, examine emergence assumptions, planting date sensitivity, developmental stages, and how the model accounts for transplanting, plastic mulch, protected production, or multiple cropping cycles. A field model that ignores the practical differences between a mature orchard and a newly planted block will produce outputs with limited value, regardless of the API design.
Soil representation deserves equal scrutiny. Many services rely on generalized soil databases or a single profile assumption. This may be adequate for regional screening but weak for irrigation and salinity management. A sandy field with shallow rooting, a layered profile with restricted drainage, and a saline clay soil can receive the same weather yet require very different actions.
Review whether the API accepts field-specific values for texture by depth, field capacity, wilting point, bulk density, rooting constraints, salinity, and drainage. Just as important, determine whether these inputs influence the calculation or merely sit as descriptive metadata. A provider should be able to explain the governing assumptions, not simply state that the platform is “AI-powered.”
Weather Quality Is a Model Input, Not a Background Detail
Most crop-model errors begin with weather data, particularly when an API uses interpolated weather in areas with strong elevation changes, coastal effects, or localized convective rainfall. Check the weather source, spatial resolution, update frequency, gap-filling method, forecast horizon, and historical revision policy.
For irrigation calculations, inspect how the service derives reference ET, whether it provides the underlying weather variables, and whether users can substitute on-farm station data. For disease models, confirm the treatment of leaf wetness, canopy humidity, and rainfall duration. These variables are often more consequential than daily average temperature.
Forecast outputs need separate evaluation from historical estimates. A model may reproduce past ET reasonably well while forecast error makes a seven-day irrigation prescription unreliable. In practice, many operations should use forecast values for planning and short-term alerts, while recalculating water balance daily as observed weather and irrigation records arrive.
Validate Outputs Against Field Evidence
No crop model should move directly from an API response to an automated field instruction without validation. The appropriate validation standard depends on the consequence of the decision. A low-risk scouting priority can tolerate more uncertainty than a fertilizer recommendation or an irrigation reduction during fruit sizing.
Build validation around representative fields and management zones. Compare water-balance estimates with soil moisture trends, irrigation volumes, drainage indicators, plant water status where available, and observed crop response. Compare phenology outputs with recorded field stages. Compare nitrogen-related outputs with soil and tissue results, yield maps where credible, and known management history.
Do not validate only during average conditions. The model should be tested during heat events, rainfall interruptions, water-quality changes, salinity pressure, delayed irrigations, and other periods when agronomic decisions become difficult. These are the conditions that determine whether an API helps a field team or simply confirms what was already obvious.
It is also necessary to separate model error from execution error. A recommendation can be agronomically sound but fail because an irrigation event was skipped, an application rate was entered incorrectly, or a grower adopted the action too late. Systems should preserve the original recommendation, the decision made, the field action recorded, and the observed outcome. Without that chain, management cannot identify where performance broke down.
Evaluate the API as an Operating Component
Agronomic quality is necessary, but API integration quality determines whether the model can be used across an organization. A technical review should examine authentication, rate limits, geographic input formats, crop and field identifiers, units, time zones, versioning, documentation, and error handling. These are not minor IT details. Unit conversion mistakes between millimeters, inches, hectares, acres, kilograms, and pounds can become direct production losses.
The API should return more than a single score whenever possible. Teams need the calculation date, data sources, assumptions, confidence indicators or data-quality flags, and enough component values to investigate an unusual result. An unexplained irrigation recommendation is difficult for an agronomist to defend to a farm manager and impossible to improve systematically.
Version control is especially important. If a provider changes a crop coefficient curve, disease threshold, weather source, or model version, historical outputs may change. Organizations using model outputs for grower support, compliance reporting, lending decisions, or sustainability programs need an auditable record of which model version informed each action.
Design for Exceptions, Not Just Average Fields
The best deployment pattern is usually not a fully automated prescription engine. It is a workflow that identifies priorities, applies technically sound rules, and directs agronomists to the fields that need judgment. For example, an API can calculate daily water balance for all vineyards, while a designated alert is created only when depletion, forecast heat, salinity risk, irrigation-system capacity, and crop stage meet defined criteria.
This matters for organizations managing distributed field teams. A technical director may need one standardized protocol, but local agronomists still need the authority to document exceptions: a blocked filter, shallow roots, a disease outbreak, poor water quality, or a delayed harvest. Standardization should make exceptions visible, not suppress them.
At scale, the useful output is often a prioritized work queue rather than an individual recommendation. Which fields need irrigation verification? Which growers require a nutrition follow-up? Which blocks lack critical input data? Which agronomists have not closed high-priority actions? This is where a crop model becomes part of operating discipline rather than another dashboard.
Commercial Questions to Ask Before Procurement
Before selecting a provider, request a working test with your own fields, not a generic demonstration dataset. Define a limited crop, region, and decision workflow. Establish success measures before the test begins, such as agreement with verified crop stage, improved irrigation follow-up time, percentage of fields with complete inputs, or reduction in unmanaged alert backlog.
Ask who owns the field data and derived outputs, how long they are retained, whether data can be exported, and what happens if the contract ends. Confirm service-level expectations for data latency and API availability. If the provider supplies agronomic recommendations, clarify whether it can explain its methodology and support local calibration with your technical team.
Price should be assessed against the work required to make the model useful. A low-cost API with poor documentation, incomplete crop support, and no operational workflow can cost more than a higher-priced service that integrates cleanly and supports validation. Conversely, an advanced model may be unnecessary if the organization has not yet standardized field boundaries, crop records, irrigation logs, and action tracking.
Cropaia can support the independent agronomic review of crop-model assumptions, irrigation and nutrition logic, and the training required for field teams to interpret outputs correctly. For organizations managing grower networks or multi-farm programs, yieldsApp can turn validated model outputs into standardized protocols, assigned actions, field records, and management visibility.
The right crop model API is not the one with the longest feature list. It is the one whose assumptions are transparent, whose uncertainty is understood, and whose outputs lead to better-timed, documented field decisions.

About Post Author
